Prometheus has no built-in clustering. How do you scale it to more targets than one instance can handle, and how do you make it highly available?
By sharding: several independent Prometheus instances each scrape a different part of the estate. For high availability, let two instances scrape the same part, so the data exists twice independently.
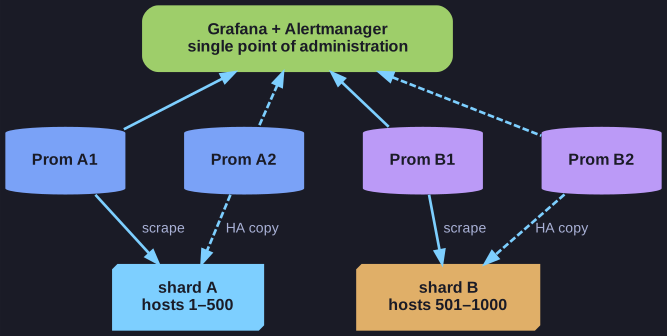
* Shards for scale, a second scraper per shard for HA, one place to administer it all. *
Prometheus always stores its data locally. There is no distributed storage and no cluster mode like Galera for MySQL. Attempts by various companies to add one have faded away.
- Federation is not a substitute. Building one central Prometheus that pulls all data from the others via federation is something the developers call a "misuse" of the feature; it looks fine on paper and causes serious problems in practice.
- Sharding works like it does for mail servers. With Consul-based discovery, make sure each instance only scrapes its own targets, not the whole setup.
- Administration stays central. Grafana can use many Prometheus instances as data sources, and one Alertmanager (which does have a real cluster mode) can take alerts from all of them.
For scale: one instance handles several thousand hosts. 1000 hosts with 250 values every 15 seconds is already a million samples per minute.
Go deeper:
 Prometheus — Federation — what federation is meant for, and what it is not.
- Shard (database architecture) — Wikipedia — the general idea behind splitting the target set.