Quiz Entry - updated: 2026.09.17
By which criteria can IAM models be classified?
By the user's view (who issues and who controls the identity), by topology (how the IAM components are distributed across systems and organisations), by data flow (federation versus provisioning), and by target group or field of use (B2E, B2C, B2B, ...).
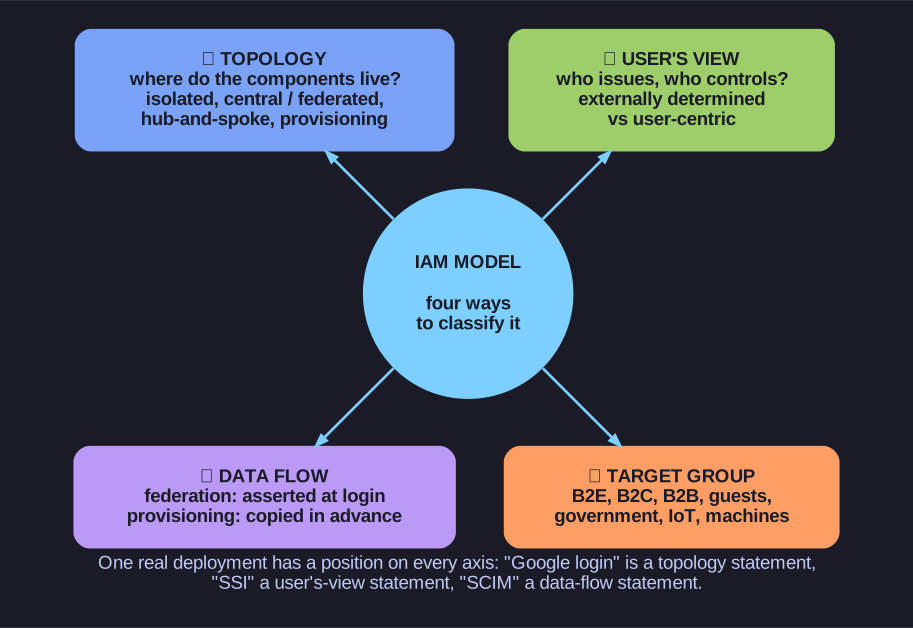
* The four classification axes; every real deployment has a position on each. *
The four taxonomies look at the same systems from different angles, and a real deployment has a position in each of them:
- User's view: who issues the identity and who controls it? This separates externally determined identities from user-centric ones.
- Topology: where do the components (identity provider, registration authority, relying party) run, and do they belong to the same organisation? This yields isolated, central, federated and brokered layouts.
- Data flow: do identities travel at login time (federation) or are they copied into the target systems beforehand (provisioning)?
- Target groups and fields of use: business-to-employee, business-to-consumer, business-to-business, guests, government, IoT and machines all impose different requirements.
Keeping the axes separate avoids a common muddle: "Google login" is a statement about topology (IdP-centred), "SSI" is a statement about the user's view (fully user-controlled), and "SCIM" is a statement about data flow (provisioning).